The World’s First Memory-Centric Inference Platform at Scale
Stacked DRAM. Scalable SRAM. Ultra-low latency.
One platform built for rack-scale AI inference and the next generation of heterogeneous accelerator pipelines.
Optimize every workload with disaggregated
Corsair + GPU pipelinesLearn more
Products
Designed around memory, built for inference.
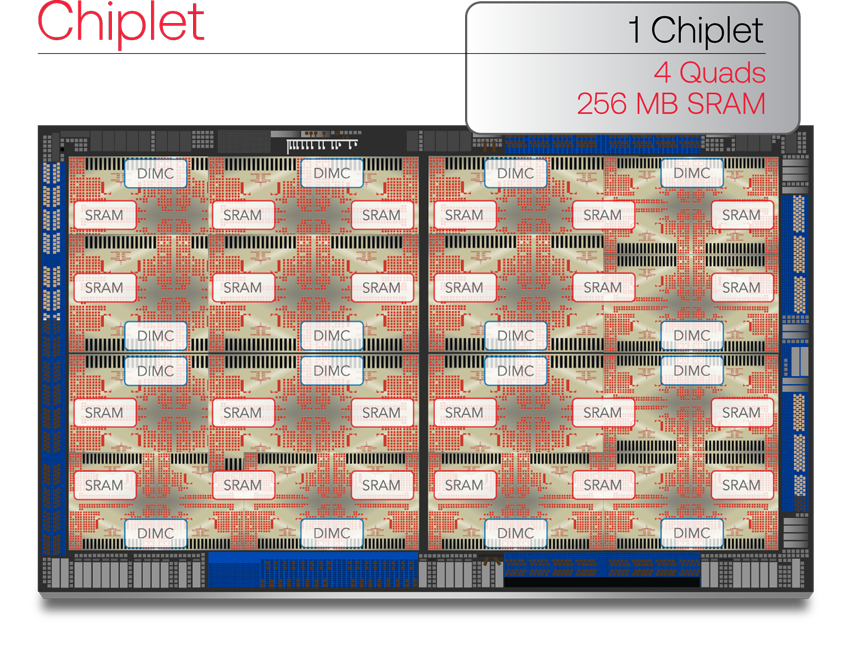
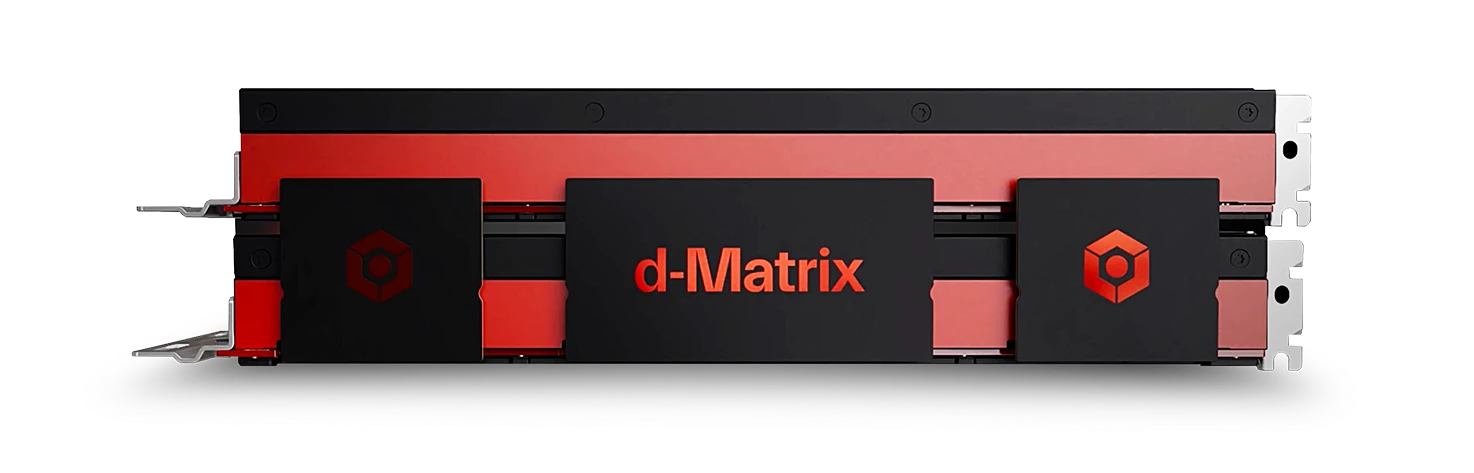
Corsair’s chiplet-based design allows SRAM to scale beyond traditional limits, supporting larger open-weight models with predictable, low-latency performance.
Contact SalesCorsair delivers a highly scalable, low-latency inference engine designed to integrate seamlessly into existing infrastructure.
Deploy across a wide range of data center environments, from standard servers to ultra-high-density racks.
Integrates into existing PCIe-based infrastructure, enabling inference using available capacity.
Lower power consumption enables larger-scale deployments supporting models up to 100B parameters.
Next-generation I/O enables rack-scale deployments
JetStream enables seamless accelerator-to-accelerator communication that preserves the extreme latency and performance benefits of Corsair.
Learn More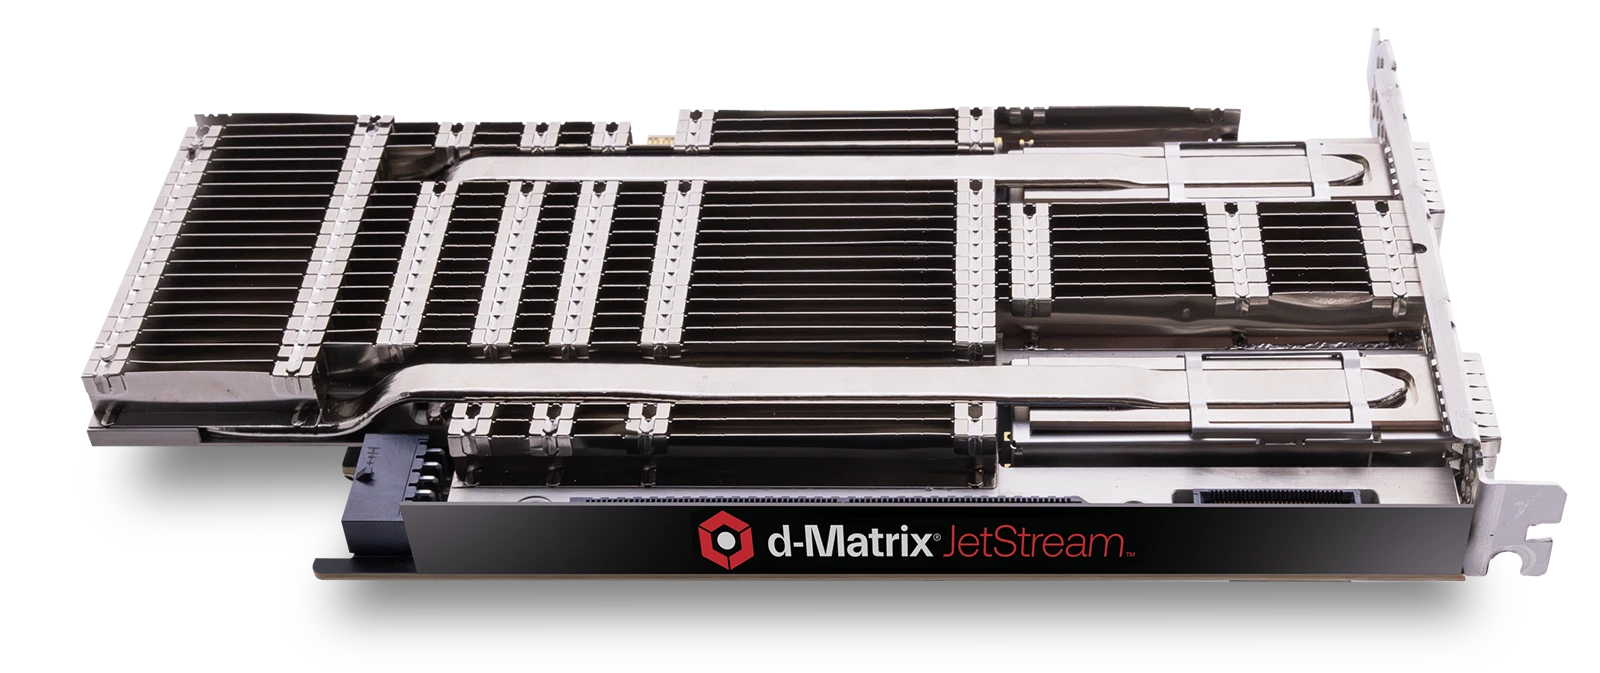
The world’s first 3D stacked DRAM solution
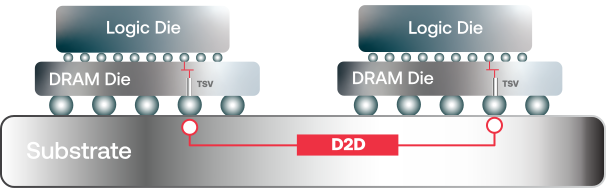
d-Matrix 3DIMC dramatically increases memory capacity without losing performance, stacking DRAM directly on the logic die for shorter data paths, higher bandwidth, and faster inference at scale.
Learn MoreAI inference hardware and software, in synergy
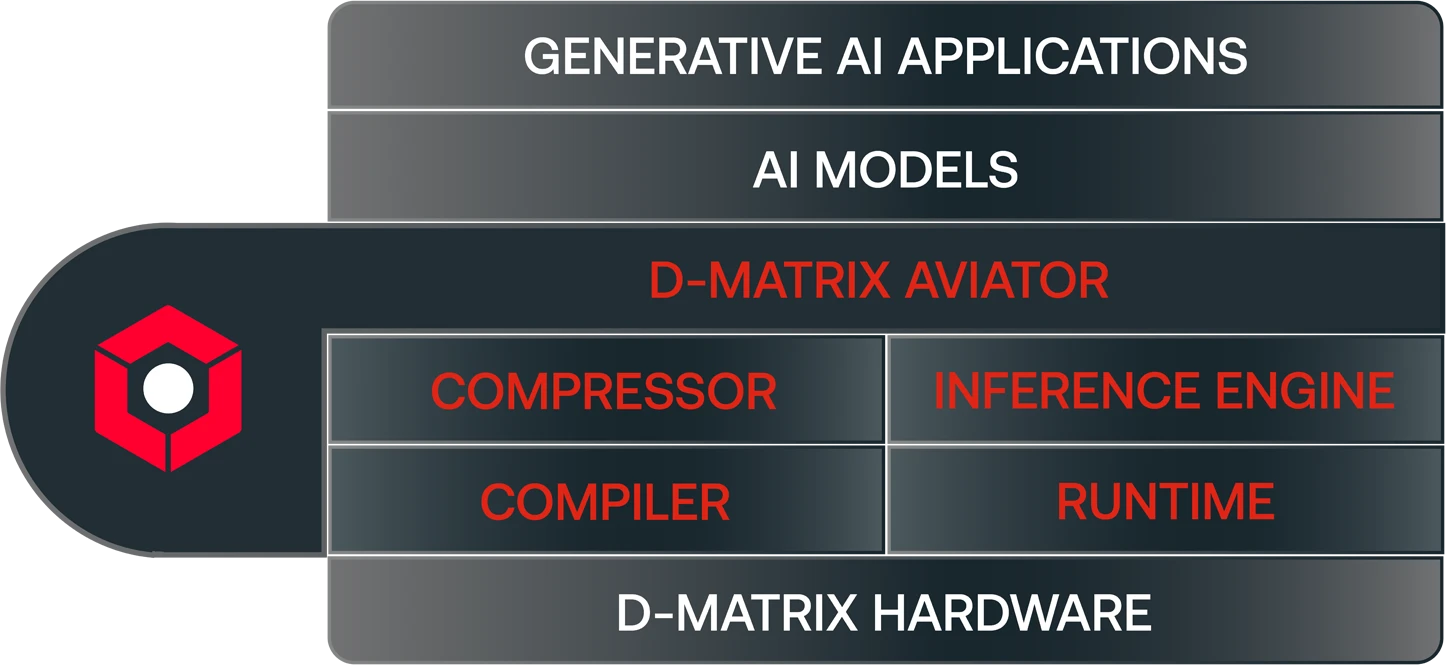
Aviator is purpose-built for Corsair.
From compiler to runtime, every layer of the d-Matrix software stack is co-designed with the hardware beneath it, so your models run faster, leaner, and with less overhead out of the box.