What if you could see exactly what d-Matrix Corsair does for your workloads before you ever pick up the phone with a sales team? That’s the idea behind d-Matrix Demo Cloud: a hosted environment built so any customer, partner, or evaluator can experience the performance of Corsair-powered inference for themselves, in minutes, on real production-grade models.
Spin up an inference endpoint on real Corsair hardware, point the OpenAI-compatible tools you already use at it, and watch heterogeneous inference perform against the workloads you care about — no infrastructure to provision and no waiting to see the performance firsthand.
d-Matrix Demo Cloud overview
We are building the d-Matrix Demo Cloud to make evaluating d-Matrix’s memory-centric AI inference accelerators as fast and effortless as possible for our customers and partners. There’s no infrastructure to stand up and no setup to wait on — the only thing standing between you, and an inference call is generating an API key. We give evaluators an OpenAI-compatible gateway, a curated model catalog, and the right level of observability to judge performance for themselves. You can explore both full-model inference on Corsair servers as well as heterogenous disaggregated inference on GPU + Corsair servers.
A home dashboard gets you oriented fast. Every demo tenant ships with a pre-provisioned workspace. From the moment you log in, you can see what’s deployed, what’s live, and where to go next.
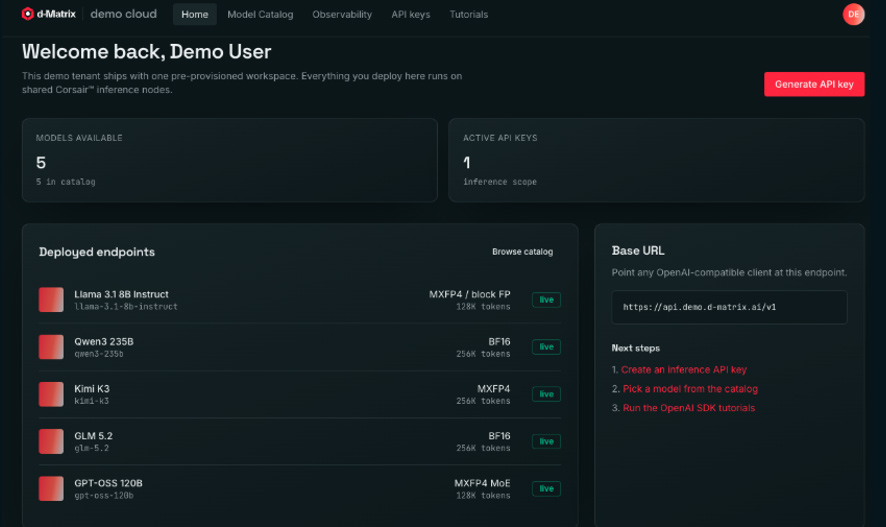
Self-service API key management, so you’re not waiting on a support ticket to start testing.
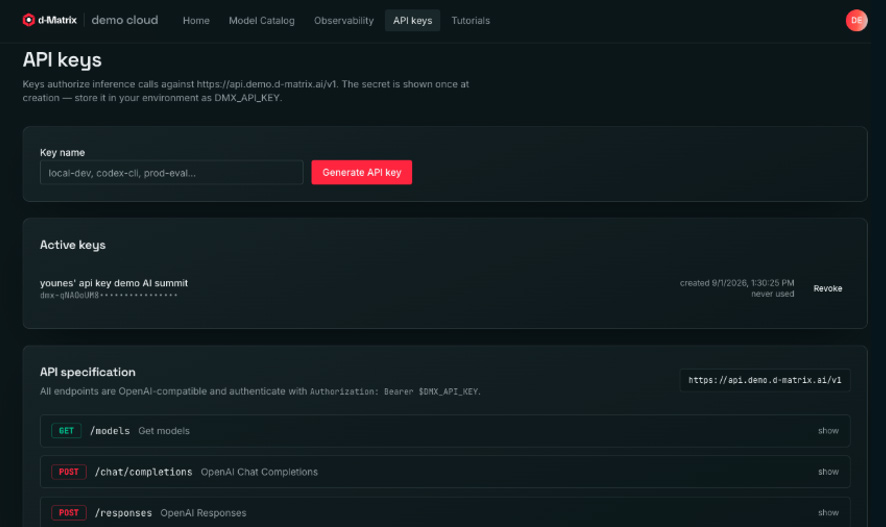
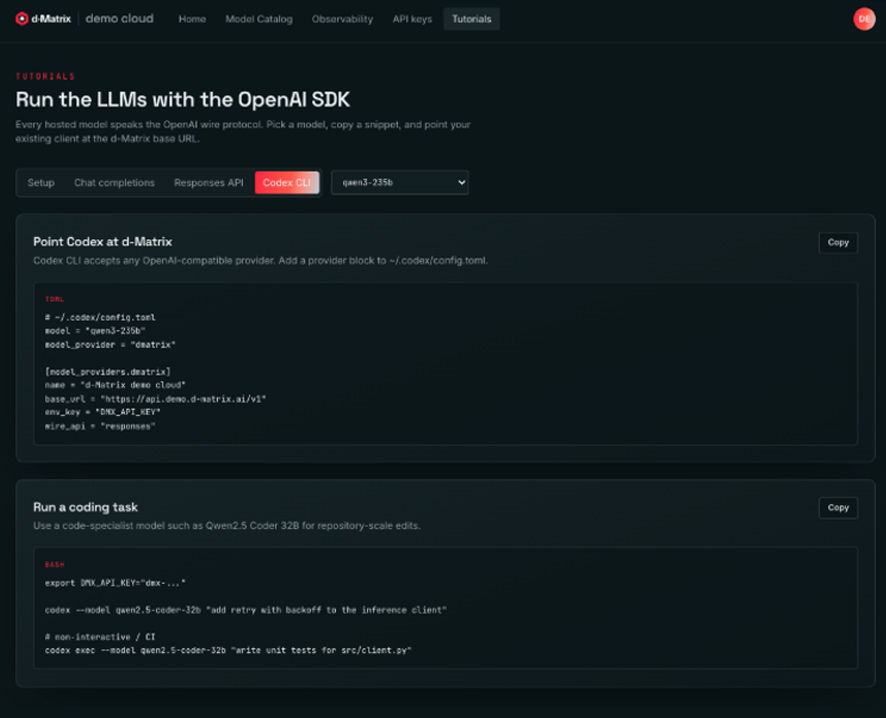
Drop-in compatibility with the tools you already use. Because every hosted model speaks the OpenAI wire protocol, switching your existing client — chat completions, the Responses API, or an agentic coding tool like Codex CLI — over to d-Matrix is a config change, not a rewrite.
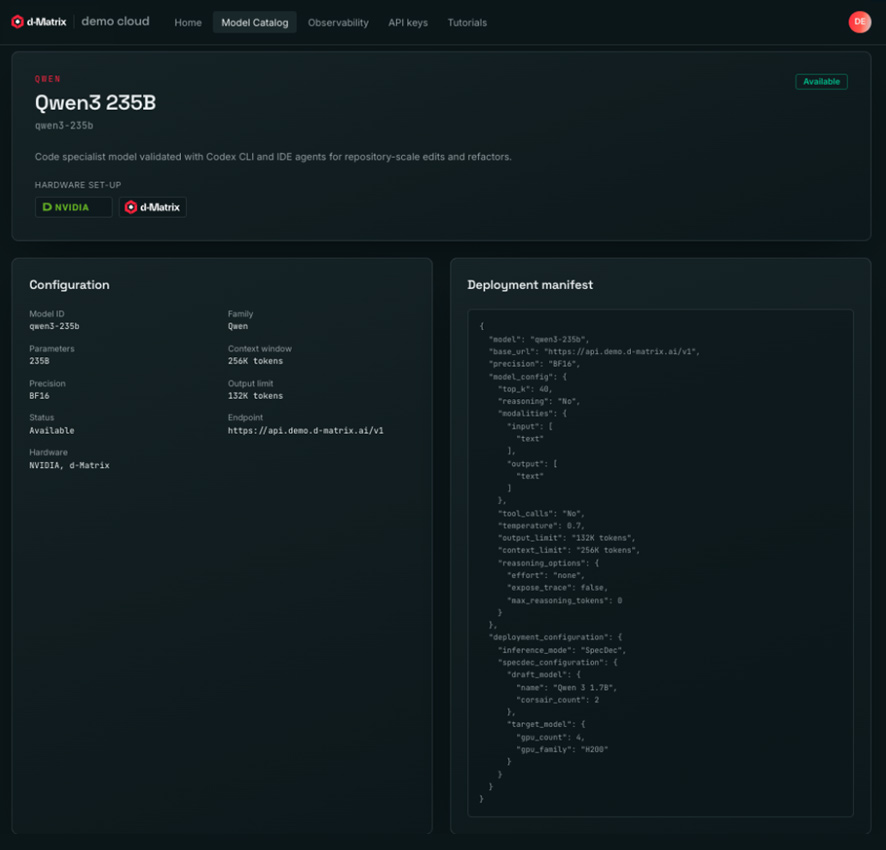
Heterogenous Speculative Decoding Inference Endpoints
Heterogeneous disaggregated Speculative Decoding (SpecD) splits the draft and target models — a small draft model running on Corsair proposes tokens, a larger target model running on GPU verifies them. Demo Cloud runs this with full orchestration across Corsair and GPU nodes.
The d-Matrix Demo Cloud inference endpoints come with pre-vetted deployment configurations for disaggregated SpecD inference mode, compute/memory allocation, and compatibility with chat completions and the Responses API — the tuning work is done before you ever send a request.
What’s Next?
At the AI Infra Summit 2026, we’re showing what the d-Matrix Demo Cloud lets you do. Visit our booth to learn more and see it in action. In the meantime:
Sign up for the d-Matrix Demo Cloud Waitlist