Oct 12, 2026 d-Matrix Announces Squadron Compute Clusters for AI Inference at Data Center Scale Read More >
Sep 10, 2026 d-Matrix Adopts NVIDIA NVLink Fusion Rackscale Infrastructure for Ultra-Low Latency AI Inference Read More >
Sep 10, 2026 Startup d-Matrix Will Pair Its Raptor Memory-Based XPU To Nvidia Rackscale Iron Read on The Next Platform ↗
Oct 12, 2026 Accelerating attention-FFN disaggregation with Corsair and Nvidia H100: inside the industry’s first ultra-low latency heterogeneous pipeline Read More >
Sep 17, 2026 Frontier class ultra-low-latency rack-scale inference with Raptor XPUs and NVLINK Fusion Read More >
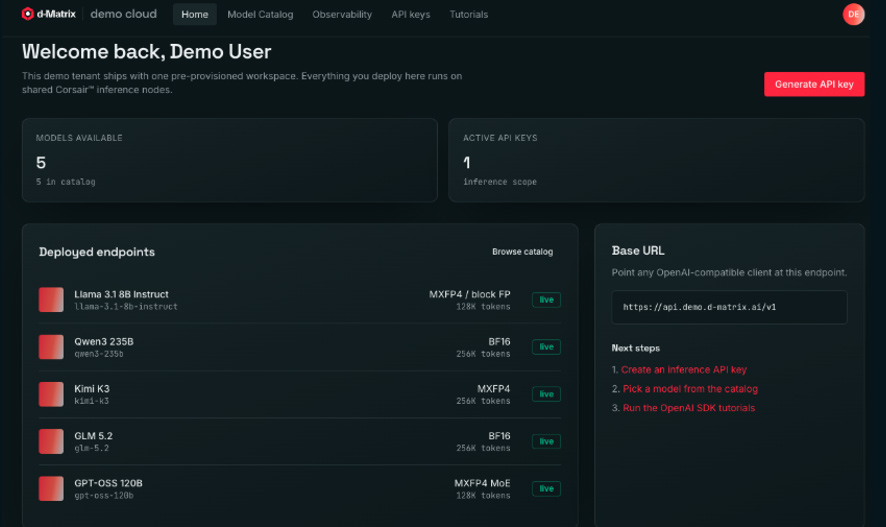
Sep 15, 2026 Introducing d-Matrix Demo Cloud: Ultra Low Latency Inference, Ready to Test in Minutes Read More >