d-Matrix
  • Technology
  • Product
    • Aviator
    • Corsair at Rack Scale
    • JetStream
    • 3D DRAM
  • Solutions
    • Voice
    • Security
    • Optimization
    • Code Generation
  • Resources
    • Blog
    • Events
  • Company
    • About
    • Careers
    • Newsroom
    • Blog

d-Matrix Blog

Featured

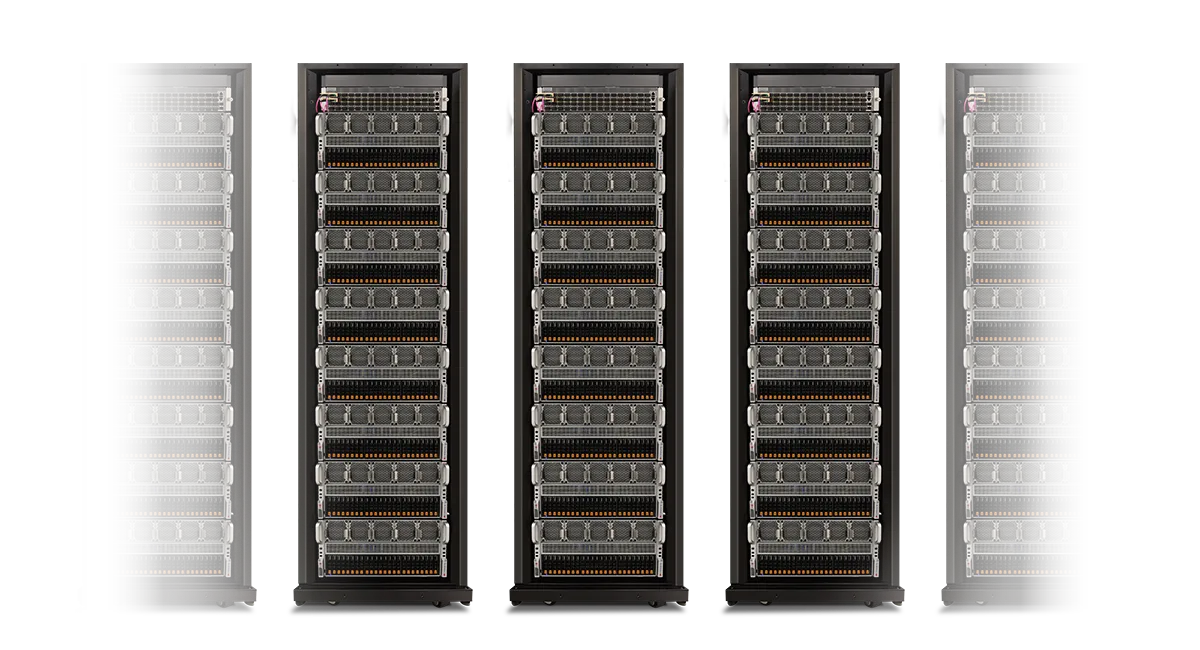
Scaling AI the Right Way: Introducing Our Rack-Level Inference Solution  

Scaling AI the Right Way: Introducing Our Rack-Level Inference Solution  

October 14, 2025
What is AI Inference and why it matters in the age of Generative AI

What is AI Inference and why it matters in the age of Generative AI

June 4, 2025
The Complete Recipe to Unlock AI Reasoning at Enterprise Scale

The Complete Recipe to Unlock AI Reasoning at Enterprise Scale

February 13, 2025
Accelerating attention-FFN disaggregation with Corsair and Nvidia H100: inside the industry’s first ultra-low latency heterogeneous pipeline 

Accelerating attention-FFN disaggregation with Corsair and Nvidia H100: inside the industry’s first ultra-low latency heterogeneous pipeline 

Disaggregated AI pipelines have offered an immediate path toward more efficient, extremely low-latency interactive experiences. This includes implementing techniques like prefill/decode disaggregation, speculative decoding, and attention-FFN disaggregation. We’ve already proven… Read More
October 12, 2026
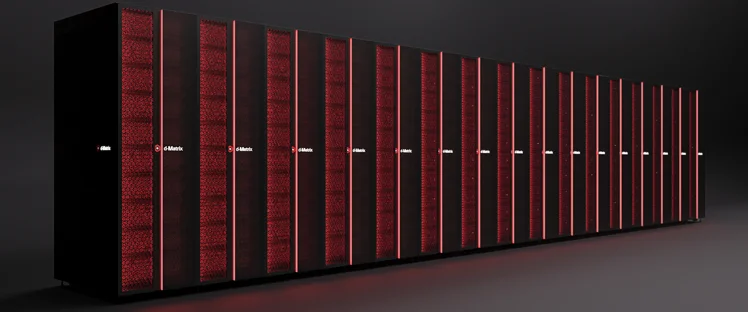
d-Matrix Announces Squadron Compute Clusters for  AI Inference at Data Center Scale

d-Matrix Announces Squadron Compute Clusters for AI Inference at Data Center Scale

d-Matrix Recognized on Fast Company’s Next Big Things in Tech List

d-Matrix Recognized on Fast Company’s Next Big Things in Tech List

Frontier class ultra-low-latency rack-scale inference with Raptor XPUs and NVLINK Fusion

Frontier class ultra-low-latency rack-scale inference with Raptor XPUs and NVLINK Fusion

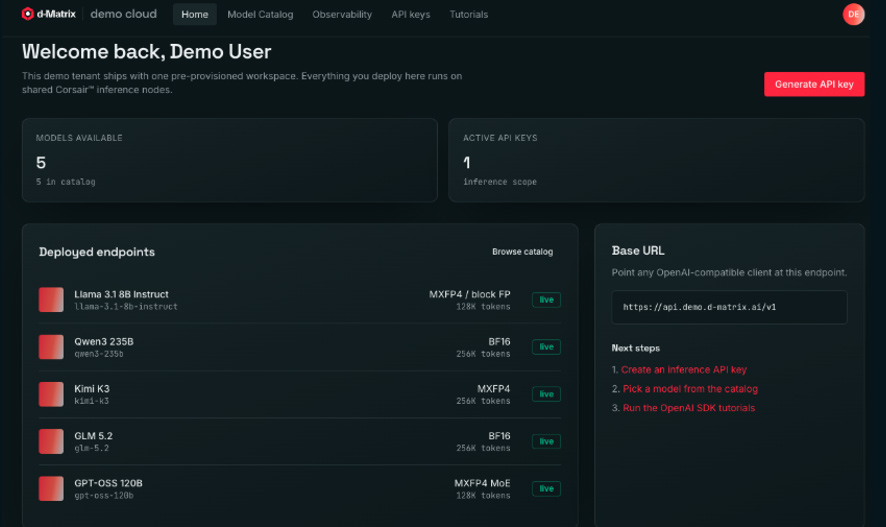
Introducing d-Matrix Demo Cloud: Ultra Low Latency Inference, Ready to Test in Minutes

Introducing d-Matrix Demo Cloud: Ultra Low Latency Inference, Ready to Test in Minutes

d-Matrix Adopts NVIDIA NVLink Fusion Rackscale Infrastructure for Ultra-Low Latency AI Inference

d-Matrix Adopts NVIDIA NVLink Fusion Rackscale Infrastructure for Ultra-Low Latency AI Inference

Chip startup d-Matrix to use Nvidia chip-linking tech in AI servers

Chip startup d-Matrix to use Nvidia chip-linking tech in AI servers

View All Posts >

Trending

Blazing the Trail Toward More Scalable, Affordable AI with 3DIMC 

How to Bridge Speed and Scale: Redefining AI Inference with Ultra-Low Latency Batched Throughput

Going Vertical: Why we created a 3D DRAM solution to advance low latency AI inference

Transforming AI: d-Matrix’s Pivotal Moments in Pursuit of Gen AI Inference At Scale

What is AI Inference and why it matters in the age of Generative AI

Featured Video

The DeepSeek Moment

In this short talk, d-Matrix CTO Sudeep Bhoja discusses the release of the Deep Seek R1 model, highlighting its impact on inference compute. He discusses the evolution of reasoning models and the significance of inference time compute in enhancing model performance.

Learn more about d-Matrix
From the Media

d-Matrix Announces Squadron Compute Clusters for AI Inference at Data Center Scale

d-Matrix Recognized on Fast Company’s Next Big Things in Tech List

d-Matrix | Nvidia logos

d-Matrix Adopts NVIDIA NVLink Fusion Rackscale Infrastructure for Ultra-Low Latency AI Inference

Chip startup d-Matrix to use Nvidia chip-linking tech in AI servers

Bloomberg logo

d-Matrix Joins Nvidia’s AI Inference Push

Startup d-Matrix Will Pair Its Raptor Memory-Based XPU To Nvidia Rackscale Iron

View all media articles > For all press inquiries, please email pr@d-matrix.ai>
Transforming AI from
unsustainable to attainable.
  • Technology
  • Product
  • Solutions
  • About
  • Careers
  • Blog
  • Newsroom
  • Newsletter
  • Media Kit
  • Contact
  • Privacy Policy
  • Terms of Use
© d-Matrix, Inc. 2026
Follow us: X Twitter Logo Streamline Icon: https://streamlinehq.com